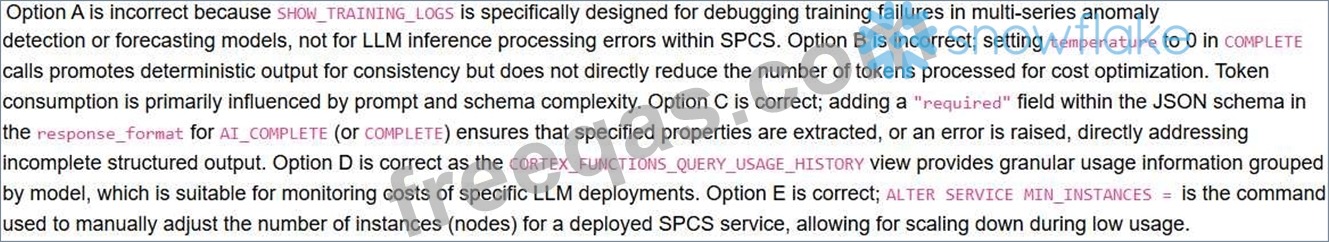
An ML Engineer deploys a custom fine-tuned LLM on Snowpark Container Services (SPCS) to process multiple independent text streams, generating structured output. The team observes that some streams fail to process, leading to incomplete results, and they also want to effectively monitor the cost of their deployment. Which actions are appropriate for troubleshooting and cost management in this scenario?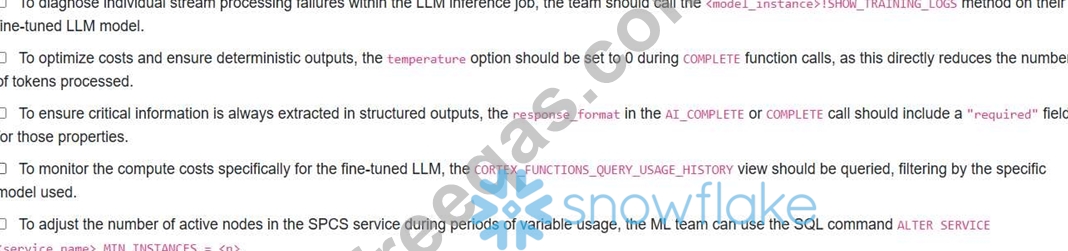
A machine learning engineering team is evaluating two different configurations of a Retrieval Augmented Generation (RAG) application. uses for generation, while uses 'mistral-7b' with a refined prompt for the same task. They aim to compare the and 'groundedness' of the generated responses, as well as the efficiency of context retrieval. Which of the following steps are crucial for setting up AI Observability in Snowflake to facilitate a meaningful side-by-side comparison and assess these specific metrics?
A data application developer is building a Streamlit chat application within Snowflake. This application uses a RAG pattern to answer user questions about a knowledge base, leveraging a Cortex Search Service for retrieval and an LLM for generating responses. The developer wants to ensure responses are relevant, concise, and structured. Which of the following practices are crucial when integrating Cortex Search with Snowflake Cortex LLM functions like AI_COMPLETE for this RAG chatbot?
An ML engineer is planning a fine-tuning project for a
llama3.1-8b
model to summarize long customer support tickets. They are considering the impact of dataset size and max_epochs on cost and performance, as well as the behavior of the fine-tuned model for inference. Which statements about cost and performance in Snowflake Cortex Fine-tuning are true? (Select all that apply)