FreeQAs
 Request Exam  Contact
  • Home
  • View All Exams
  • New QA's
  • Upload
PRACTICE EXAMS:
  • Oracle
  • Fortinet
  • Juniper
  • Microsoft
  • Cisco
  • Citrix
  • CompTIA
  • VMware
  • ISC
  • SAP
  • EMC
  • PMI
  • HP
  • Salesforce
  • Other
  • Oracle
    Oracle
  • Fortinet
    Fortinet
  • Juniper
    Juniper
  • Microsoft
    Microsoft
  • Cisco
    Cisco
  • Citrix
    Citrix
  • CompTIA
    CompTIA
  • VMware
    VMware
  • ISC
    ISC
  • SAP
    SAP
  • EMC
    EMC
  • PMI
    PMI
  • HP
    HP
  • Salesforce
    Salesforce
  1. Home
  2. CompTIA Certification
  3. DY0-001 Exam
  4. CompTIA.DY0-001.v2026-06-07.q59 Dumps
  • ««
  • «
  • …
  • 4
  • 5
  • 6
  • 7
  • 8
  • 9
  • 10
  • 11
  • 12
  • 13
  • »
Download Now

Question 41

The most likely concern with a one-feature, machine-learning model is high error due to:

Correct Answer: A
A model with only one feature is unlikely to capture the true complexity of the data's underlying relationships, leading to systematic underfitting - i.e., high bias.
insert code

Question 42

A data scientist is using the following confusion matrix to assess model performance:
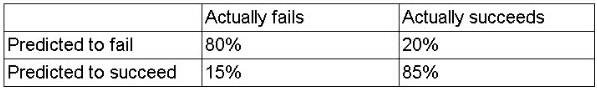
The model is predicting whether a delivery truck will be able to make 200 scheduled delivery stops. Every time the model is correct, the company saves an hour in planning and scheduling of maintenance work. Every time the model is wrong, the company loses four hours of delivery time for the truck. Which of the following is the net model impact for the company?

Correct Answer: A
Treat each "predicted-to-fail" and "predicted-to-succeed" row as coming from 100 cases apiece (200 total).
insert code

Question 43

Which of the following does k represent in the k-means model?

Correct Answer: C
# In k-means clustering, k represents the number of clusters that the algorithm will attempt to form. The algorithm partitions the dataset into k distinct, non-overlapping clusters based on feature similarity. Each cluster has a centroid, and the algorithm aims to minimize the intra-cluster variance.
Why the other options are incorrect:
* A: Number of tests is unrelated to the k-means algorithm.
* B: Data splits refer to cross-validation or train/test splits, not k in k-means.
* D: Distance between features is computed during clustering but is not what "k" represents.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 4.2:"In k-means clustering, k denotes the number of clusters into which the dataset will be partitioned."
* Introduction to Machine Learning, Chapter 6:"The 'k' in k-means specifies how many groupings the algorithm will seek to discover based on proximity in feature space."
-
insert code

Question 44

Which of the following is a key difference between KNN and k-means machine-learning techniques?

Correct Answer: D
# K-Nearest Neighbors (KNN) is a supervised machine learning algorithm used primarily for classification and regression. It labels a new instance by majority vote (or averaging, in regression) of its k-nearest labeled neighbors.
# k-Means is an unsupervised learning algorithm used for clustering. It partitions unlabeled data into k groups based on feature similarity, using centroids.
Thus, the key difference is in their purpose:
* KNN # Classification (Supervised)
* K-Means # Clustering (Unsupervised)
Why the other options are incorrect:
* A: Both can technically operate on continuous or categorical data (with preprocessing).
* B: This is not a meaningful or standardized distinction.
* C: This reverses the actual roles. k-means finds centroids; KNN finds nearest neighbors.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 4.1 (Classification vs. Clustering):"KNN is a supervised learning algorithm for classification tasks. K-means is an unsupervised clustering technique that groups data by proximity to centroids."
* Data Science Handbook, Chapter 5:"One key distinction: KNN uses labeled data to classify or regress; k-means uses unlabeled data to identify groupings."
-
insert code

Question 45

A data scientist has built a model that provides the likelihood of an error occurring in a factory. The historical accuracy of the model is 90%. At a specific factory, the model is reporting a likelihood score of 0.90. Which of the following explains a confidence score of 0.90?


Correct Answer: D
# A likelihood score of 0.90 indicates the model's confidence that an error will occur in this particular instance. Interpreted probabilistically, it means that if this scenario happened 100 times, the model would expect an error in 90 of those cases.
Why the other options are incorrect:
* A: Confuses confidence with recall or precision.
* B: Refers to model sampling performance, not instance-level prediction.
* C: Implies a prediction of actual factory errors - not the model's forecast probability.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 3.2:"A confidence score in a classification model indicates the model's belief in the outcome of a specific prediction."
-
insert code
  • ««
  • «
  • …
  • 4
  • 5
  • 6
  • 7
  • 8
  • 9
  • 10
  • 11
  • 12
  • 13
  • »
[×]

Download PDF File

Enter your email address to download CompTIA.DY0-001.v2026-06-07.q59 Dumps

Email:

FreeQAs

Our website provides the Largest and the most Latest vendors Certification Exam materials around the world.

Using dumps we provide to Pass the Exam, we has the Valid Dumps with passing guranteed just which you need.

  • DMCA
  • About
  • Contact Us
  • Privacy Policy
  • Terms & Conditions
©2026 FreeQAs

www.freeqas.com materials do not contain actual questions and answers from Cisco's certification exams.