FreeQAs
 Request Exam  Contact
  • Home
  • View All Exams
  • New QA's
  • Upload
PRACTICE EXAMS:
  • Oracle
  • Fortinet
  • Juniper
  • Microsoft
  • Cisco
  • Citrix
  • CompTIA
  • VMware
  • ISC
  • SAP
  • EMC
  • PMI
  • HP
  • Salesforce
  • Other
  • Oracle
    Oracle
  • Fortinet
    Fortinet
  • Juniper
    Juniper
  • Microsoft
    Microsoft
  • Cisco
    Cisco
  • Citrix
    Citrix
  • CompTIA
    CompTIA
  • VMware
    VMware
  • ISC
    ISC
  • SAP
    SAP
  • EMC
    EMC
  • PMI
    PMI
  • HP
    HP
  • Salesforce
    Salesforce
  1. Home
  2. CompTIA Certification
  3. DY0-001 Exam
  4. CompTIA.DY0-001.v2026-06-07.q59 Dumps
  • «
  • 1
  • 2
  • 3
  • 4
  • 5
  • 6
  • 7
  • 8
  • 9
  • 10
  • …
  • »
  • »»
Download Now

Question 11

A data scientist is designing a real-time machine-learning model that classifies a user based on initial behavior. The run times of these models are provided in the following table:
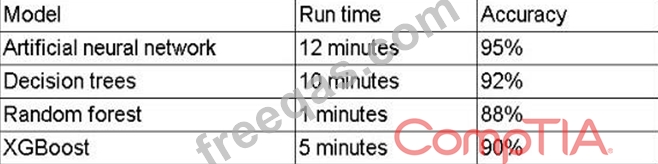
Which of the following models should the data scientist recommend for deployment?

Correct Answer: B
For a real-time application, inference latency is critical. Although its accuracy (88%) is slightly lower than the others, the random forest's 1-minute run time is by far the fastest, making it the only model capable of meeting real-time responsiveness.
insert code

Question 12

A data scientist is building a forecasting model for the price of copper. The only input in this model is the daily price of copper for the last ten years. Which of the following forecasting techniques is the most appropriate for the data scientist to use?

Correct Answer: A
# An Autoregressive (AR) model is ideal when past values of a time series are used to predict future values.
Since the only input is historical price data of copper, AR is the most appropriate technique.
Why the other options are incorrect:
* B: Moving average smooths noise but doesn't model the dependencies for prediction.
* C: Dynamic time warping is used for measuring similarity between time series, not forecasting.
* D: Relative strength is a financial metric used for comparing asset performance - not a forecasting technique.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 3.5:"Autoregressive models are used when the goal is to predict future values based solely on past values in a univariate time series."
* Time Series Analysis and Forecasting, Chapter 5:"AR models capture the temporal dependencies in time series data and are foundational in time-based prediction."
-
insert code

Question 13

A data scientist is deploying a model that needs to be accessed by multiple departments with minimal development effort by the departments. Which of the following APIs would be best for the data scientist to use?

Correct Answer: D
RESTful APIs use standard HTTP methods and lightweight data formats (typically JSON), making them easy for diverse teams to integrate with minimal effort and without heavy tooling.
insert code

Question 14

The most likely concern with a one-feature, machine-learning model is high error due to:

Correct Answer: A
# A one-feature model is likely to be overly simplistic and may not capture the true complexity of the target variable. This leads to underfitting, which is associated with high bias - the model consistently misses the mark regardless of the data.
Why the other options are incorrect:
* B: High dimensionality is not a concern in this case - the model has too few features.
* C: Variance refers to overfitting - more common in overly complex models.
* D: Probability is a modeling technique, not a source of error.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 4.2:"Models with insufficient features tend to underfit and exhibit high bias due to their inability to represent complex relationships."
* Bias-Variance Tradeoff - Data Science Textbook:"A high-bias model makes strong assumptions and is typically too simple to capture the underlying patterns in data."
insert code

Question 15

A data scientist is performing a linear regression and wants to construct a model that explains the most variation in the data. Which of the following should the data scientist maximize when evaluating the regression performance metrics?


Correct Answer: B
# R² (coefficient of determination) quantifies how much of the variance in the dependent variable is explained by the model. A higher R² means a better fit to the data, making it the metric to maximize for explanatory power in regression analysis.
Why the other options are incorrect:
* A: Accuracy is used in classification, not regression.
* C: p-values test statistical significance of coefficients, not overall model fit.
* D: AUC (Area Under the Curve) applies to classification models, not regression.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 3.2:"R² is a regression performance metric indicating the proportion of variance explained by the independent variables."
insert code
  • «
  • 1
  • 2
  • 3
  • 4
  • 5
  • 6
  • 7
  • 8
  • 9
  • 10
  • …
  • »
  • »»
[×]

Download PDF File

Enter your email address to download CompTIA.DY0-001.v2026-06-07.q59 Dumps

Email:

FreeQAs

Our website provides the Largest and the most Latest vendors Certification Exam materials around the world.

Using dumps we provide to Pass the Exam, we has the Valid Dumps with passing guranteed just which you need.

  • DMCA
  • About
  • Contact Us
  • Privacy Policy
  • Terms & Conditions
©2026 FreeQAs

www.freeqas.com materials do not contain actual questions and answers from Cisco's certification exams.