FreeQAs
 Request Exam  Contact
  • Home
  • View All Exams
  • New QA's
  • Upload
PRACTICE EXAMS:
  • Oracle
  • Fortinet
  • Juniper
  • Microsoft
  • Cisco
  • Citrix
  • CompTIA
  • VMware
  • ISC
  • SAP
  • EMC
  • PMI
  • HP
  • Salesforce
  • Other
  • Oracle
    Oracle
  • Fortinet
    Fortinet
  • Juniper
    Juniper
  • Microsoft
    Microsoft
  • Cisco
    Cisco
  • Citrix
    Citrix
  • CompTIA
    CompTIA
  • VMware
    VMware
  • ISC
    ISC
  • SAP
    SAP
  • EMC
    EMC
  • PMI
    PMI
  • HP
    HP
  • Salesforce
    Salesforce
  1. Home
  2. Databricks Certification
  3. Databricks-Certified-Professional-Data-Engineer Exam
  4. Databricks.Databricks-Certified-Professional-Data-Engineer.v2025-10-27.q109 Dumps
  • ««
  • «
  • …
  • 14
  • 15
  • 16
  • 17
  • 18
  • 19
  • 20
  • 21
  • 22
  • 23
  • »
Download Now

Question 86

Data science team has requested they are missing a column in the table called average price, this can be calculated using units sold and sales amt, which of the following SQL statements allow you to reload the data with additional column

Correct Answer: B
Explanation
1.CREATE OR REPLACE TABLE sales
2.AS SELECT *, salesAmt/unitsSold as avgPrice FROM sales
The main difference between INSERT OVERWRITE and CREATE OR REPLACE TABLE(CRAS) is that CRAS can modify the schema of the table, i.e it can add new columns or change data types of existing columns. By default INSERT OVERWRITE only overwrites the data.
INSERT OVERWRITE can also be used to overwrite schema, only when
spark.databricks.delta.schema.autoMerge.enabled is set true if this option is not enabled and if there is a schema mismatch command will fail.
insert code

Question 87

A data ingestion task requires a one-TB JSON dataset to be written out to Parquet with a target part-file size of
512 MB. Because Parquet is being used instead of Delta Lake, built-in file-sizing features such as Auto-Optimize & Auto-Compaction cannot be used.
Which strategy will yield the best performance without shuffling data?

Correct Answer: B
The key to efficiently converting a large JSON dataset to Parquet files of a specific size without shuffling data lies in controlling the size of the output files directly.
* Settingspark.sql.files.maxPartitionBytesto 512 MB configures Spark to process data in chunks of 512 MB. This setting directly influences the size of the part-files in the output, aligning with the target file size.
* Narrow transformations (which do not involve shuffling data across partitions) can then be applied to this data.
* Writing the data out to Parquet will result in files that are approximately the size specified by spark.sql.files.maxPartitionBytes, in this case, 512 MB.
* The other options involve unnecessary shuffles or repartitions (B, C, D) or an incorrect setting for this specific requirement (E).
References:
* Apache Spark Documentation: Configuration - spark.sql.files.maxPartitionBytes
* Databricks Documentation on Data Sources: Databricks Data Sources Guide
insert code

Question 88

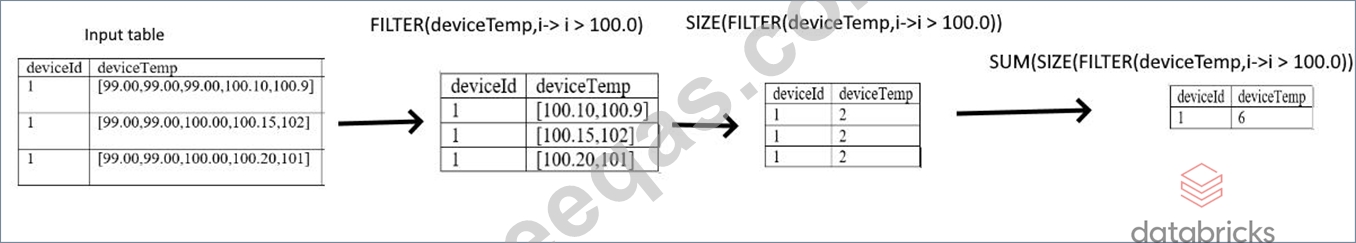
You were asked to identify number of times a temperature sensor exceed threshold temperature (100.00) by each device, each row contains 5 readings collected every 5 minutes, fill in the blank with the appropriate functions.
Schema: deviceId INT, deviceTemp ARRAY<double>, dateTimeCollected TIMESTAMP

SELECT deviceId, __ (__ (__(deviceTemp], i -> i > 100.00)))
FROM devices
GROUP BY deviceId
Correct Answer: E
Explanation
FILER function can be used to filter an array based on an expression
SIZE function can be used to get size of an array
SUM is used to calculate to total by device
Diagram Description automatically generated
insert code

Question 89

A Databricks job has been configured with 3 tasks, each of which is a Databricks notebook. Task A does not depend on other tasks. Tasks B and C run in parallel, with each having a serial dependency on Task A.
If task A fails during a scheduled run, which statement describes the results of this run?

Correct Answer: D
When a Databricks job runs multiple tasks with dependencies, the tasks are executed in a dependency graph.
If a task fails, the downstream tasks that depend on it are skipped and marked as Upstream failed. However, the failed task may have already committed some changes to the Lakehouse before the failure occurred, and those changes are not rolled back automatically. Therefore, the job run may result in a partial update of the Lakehouse. To avoid this, you can use the transactional writes feature of Delta Lake to ensure that the changes are only committed when the entire job run succeeds. Alternatively, you can use the Run if condition to configure tasks to run even when some or all of their dependencies have failed, allowing your job to recover from failures and continue running. References:
* transactional writes: https://docs.databricks.com/delta/delta-intro.html#transactional-writes
* Run if: https://docs.databricks.com/en/workflows/jobs/conditional-tasks.html
insert code

Question 90

A SQL Dashboard was built for the supply chain team to monitor the inventory and product orders, but all of the timestamps displayed on the dashboards are showing in UTC format, so they requested to change the time zone to the location of New York. How would you approach resolving this issue?
Correct Answer: D
Explanation
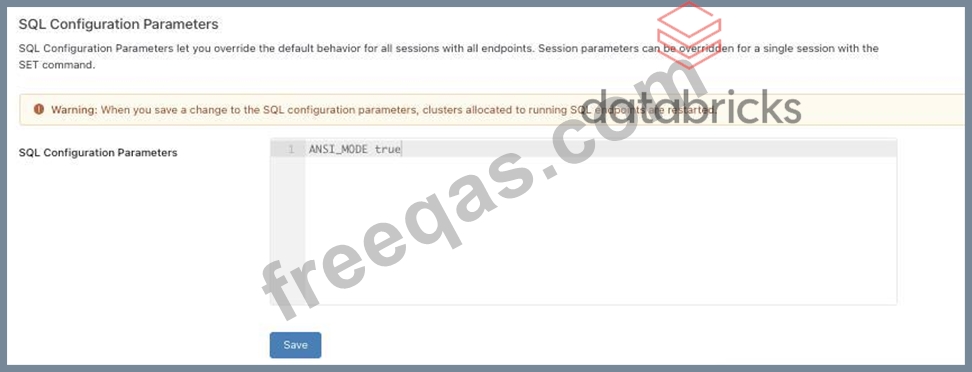
The answer is, Under SQL Admin Console, set the SQL configuration parameter time zone to America/New_York Here are steps you can take this to configure, so the entire dashboard is changed without changing individual queries Configure SQL parameters To configure all warehouses with SQL parameters:
1.Click Settings at the bottom of the sidebar and select SQL Admin Console.
2.Click the SQL Warehouse Settings tab.
3.In the SQL Configuration Parameters textbox, specify one key-value pair per line. Sepa-rate the name of the parameter from its value using a space. For example, to ena-ble ANSI_MODE:
Graphical user interface, text, application Description automatically generated

Similarly, we can add a line in the SQL Configuration parameters
timezone America/New_York
SQL configuration parameters | Databricks on AWS
insert code
  • ««
  • «
  • …
  • 14
  • 15
  • 16
  • 17
  • 18
  • 19
  • 20
  • 21
  • 22
  • 23
  • »
[×]

Download PDF File

Enter your email address to download Databricks.Databricks-Certified-Professional-Data-Engineer.v2025-10-27.q109 Dumps


Email:

FreeQAs

Our website provides the Largest and the most Latest vendors Certification Exam materials around the world.

Using dumps we provide to Pass the Exam, we has the Valid Dumps with passing guranteed just which you need.

  • DMCA
  • About
  • Contact Us
  • Privacy Policy
  • Terms & Conditions
©2026 FreeQAs

www.freeqas.com materials do not contain actual questions and answers from Cisco's certification exams.