FreeQAs
 Request Exam  Contact
  • Home
  • View All Exams
  • New QA's
  • Upload
PRACTICE EXAMS:
  • Oracle
  • Fortinet
  • Juniper
  • Microsoft
  • Cisco
  • Citrix
  • CompTIA
  • VMware
  • ISC
  • SAP
  • EMC
  • PMI
  • HP
  • Salesforce
  • Other
  • Oracle
    Oracle
  • Fortinet
    Fortinet
  • Juniper
    Juniper
  • Microsoft
    Microsoft
  • Cisco
    Cisco
  • Citrix
    Citrix
  • CompTIA
    CompTIA
  • VMware
    VMware
  • ISC
    ISC
  • SAP
    SAP
  • EMC
    EMC
  • PMI
    PMI
  • HP
    HP
  • Salesforce
    Salesforce
  1. Home
  2. Microsoft Certification
  3. DP-600 Exam
  4. Microsoft.DP-600.v2026-10-12.q204 Dumps
  • ««
  • «
  • …
  • 21
  • 22
  • 23
  • 24
  • 25
  • 26
  • 27
  • 28
  • 29
  • 30
  • …
  • »
  • »»
Download Now

Question 121

Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a Fabric tenant that contains a lakehouse named Lakehousel. Lakehousel contains a Delta table named Customer.
When you query Customer, you discover that the query is slow to execute. You suspect that maintenance was NOT performed on the table.
You need to identify whether maintenance tasks were performed on Customer.
Solution: You run the following Spark SQL statement:
DESCRIBE DETAIL customer
Does this meet the goal?

Correct Answer: A
insert code

Question 122

You have a Fabric tenant that contains a lakehouse.
You are using a Fabric notebook to save a large DataFrame by using the following code.

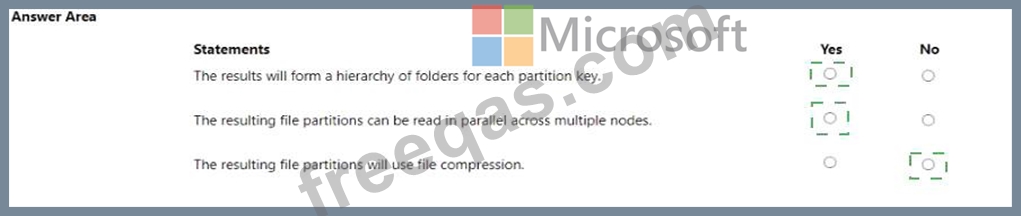
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
Correct Answer:

Explanation:
The results will form a hierarchy of folders for each partition key. - Yes The resulting file partitions can be read in parallel across multiple nodes. - Yes The resulting file partitions will use file compression. - No Partitioning data by columns such as year, month, and day, as shown in the DataFrame write operation, organizes the output into a directory hierarchy that reflects the partitioning structure. This organization can improve the performance of read operations, as queries that filter by the partitioned columns can scan only the relevant directories. Moreover, partitioning facilitates parallelism because each partition can be processed independently across different nodes in a distributed system like Spark. However, the code snippet provided does not explicitly specify that file compression should be used, so we cannot assume that the output will be compressed without additional context.
References =
DataFrame write partitionBy
Apache Spark optimization with partitioning
insert code

Question 123

You need to provide Power Bl developers with access to the pipeline. The solution must meet the following requirements:
* Ensure that the developers can deploy items to the workspaces for Development and Test.
* Prevent the developers from deploying items to the workspace for Production.
* Follow the principle of least privilege.
Which three levels of access should you assign to the developers? Each correct answer presents part of the solution. NOTE: Each correct answer is worth one point.

Correct Answer: A,C,F
insert code

Question 124

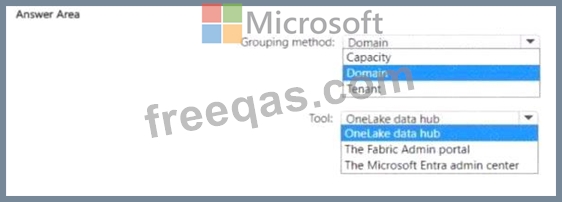
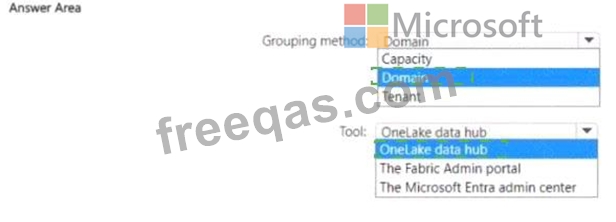
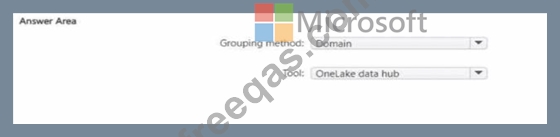
You need to recommend a solution to group the Research division workspaces.
What should you include in the recommendation? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Correct Answer:

Explanation:
insert code

Question 125

You have a Fabric tenant that contains a semantic model named Model1. Model1 contains a fact table with millions of rows of shipment data.
You need to enable partitioning to improve the query performance and manageability of Model1.
Which two tools can you use to achieve the goal? Each correct answer presents a complete solution.
NOTE: Each correct answer is worth one point.
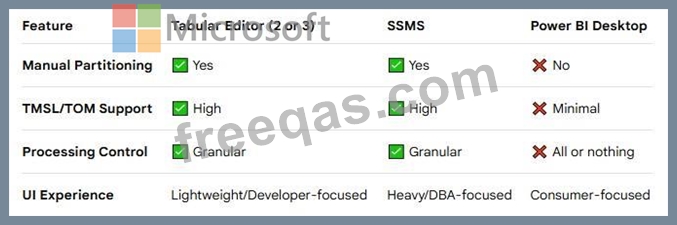
Correct Answer: A,E
The Tabular Editor and SSMS are the superior choices for managing large-scale semantic models in Microsoft Fabric. Power BI Desktop is limited because it lacks a native interface for manual partition management outside of basic Incremental Refresh.
Here is the breakdown of why and how to use these tools to optimize your million-row fact table.
Tool Comparison for Partitioning

Reference:
https://tabulareditor.com/blog/semantic-modeling-patterns-with-power-bi-and-databricks
insert code
  • ««
  • «
  • …
  • 21
  • 22
  • 23
  • 24
  • 25
  • 26
  • 27
  • 28
  • 29
  • 30
  • …
  • »
  • »»
[×]

Download PDF File

Enter your email address to download Microsoft.DP-600.v2026-10-12.q204 Dumps

Email:

FreeQAs

Our website provides the Largest and the most Latest vendors Certification Exam materials around the world.

Using dumps we provide to Pass the Exam, we has the Valid Dumps with passing guranteed just which you need.

  • DMCA
  • About
  • Contact Us
  • Privacy Policy
  • Terms & Conditions
©2026 FreeQAs

www.freeqas.com materials do not contain actual questions and answers from Cisco's certification exams.
