FreeQAs
 Request Exam  Contact
  • Home
  • View All Exams
  • New QA's
  • Upload
PRACTICE EXAMS:
  • Oracle
  • Fortinet
  • Juniper
  • Microsoft
  • Cisco
  • Citrix
  • CompTIA
  • VMware
  • ISC
  • SAP
  • EMC
  • PMI
  • HP
  • Salesforce
  • Other
  • Oracle
    Oracle
  • Fortinet
    Fortinet
  • Juniper
    Juniper
  • Microsoft
    Microsoft
  • Cisco
    Cisco
  • Citrix
    Citrix
  • CompTIA
    CompTIA
  • VMware
    VMware
  • ISC
    ISC
  • SAP
    SAP
  • EMC
    EMC
  • PMI
    PMI
  • HP
    HP
  • Salesforce
    Salesforce
  1. Home
  2. Microsoft Certification
  3. DP-600 Exam
  4. Microsoft.DP-600.v2026-10-12.q204 Dumps
  • ««
  • «
  • …
  • 4
  • 5
  • 6
  • 7
  • 8
  • 9
  • 10
  • 11
  • 12
  • 13
  • …
  • »
  • »»
Download Now

Question 36

You need to refresh the Orders table of the Online Sales department. The solution must meet the semantic model requirements. What should you include in the solution?

Correct Answer: C
destination lakehouse
insert code

Question 37

Hotspot Question
You have a Fabric eventhouse that contains a KQL database. The database contains a table named TaxiData that stores the following data.
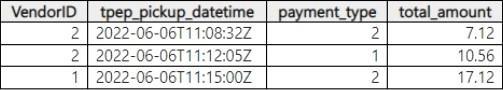
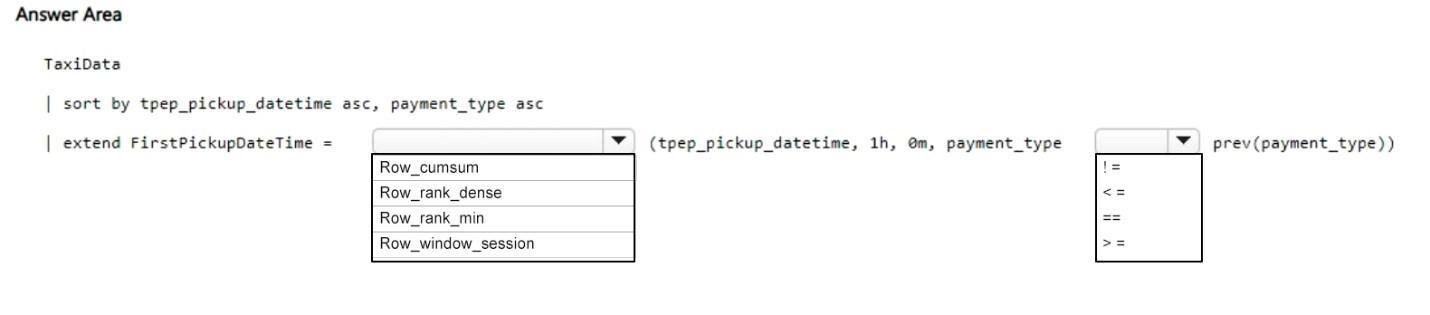
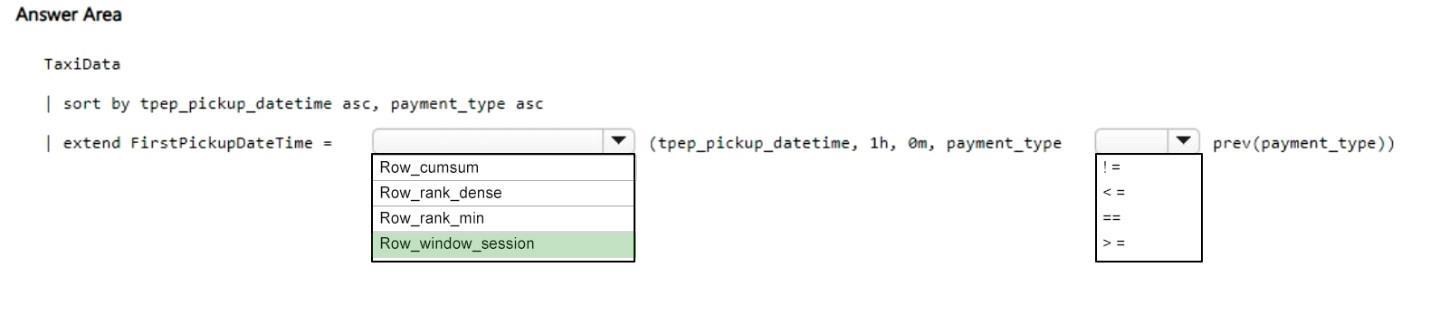
You need to create a column named FirstPickupDateTime that will contain the first value of each hour from tpep_pickup_datetime partitioned by payment_type.
How should you complete the query? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Correct Answer:

Explanation:
Box 1: Row_Window_Session
Kusto, KQL Windowing Functions - Row_Window_Session
The row_window_session function can be used to group rows of data in a time range, and will return the starting time for that range of data in each row.
Box 2: !=
Here we are using an equation, which will compare the payment_type for the current row to the one of the previous row using the prev Windowing Function. If they are not equal, the comparison will return true and trigger Row_Window_Session to begin a Row_Window_Session grouping.
insert code

Question 38

You are creating a semantic model in Microsoft Power Bl Desktop.
You plan to make bulk changes to the model by using the Tabular Model Definition Language (TMDL) extension for Microsoft Visual Studio Code.
You need to save the semantic model to a file.
Which file format should you use?

Correct Answer: A
When saving a semantic model to a file that can be edited using the Tabular Model Scripting Language (TMSL) extension for Visual Studio Code, the PBIX (Power BI Desktop) file format is the correct choice.
The PBIX format contains the report, data model, and queries, and is the primary file format for editing in Power BI Desktop. References = Microsoft's documentation on Power BI file formats and Visual Studio Code provides further clarification on the usage of PBIX files.
insert code

Question 39

You have a Fabric tenant that contains lakehouse named Lakehouse1. Lakehouse1 contains a Delta table with eight columns. You receive new data that contains the same eight columns and two additional columns.
You create a Spark DataFrame and assign the DataFrame to a variable named df. The DataFrame contains the new data. You need to add the new data to the Delta table to meet the following requirements:
* Keep all the existing rows.
* Ensure that all the new data is added to the table.
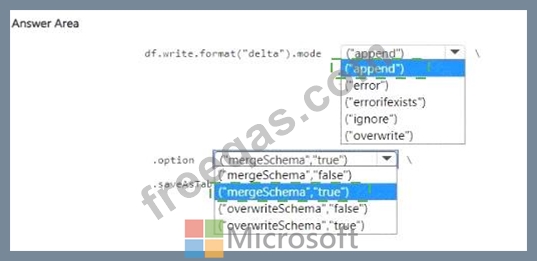
How should you complete the code? To answer, select the appropriate options in the answer area.
Correct Answer:

Explanation:

o add new data to the Delta table while meeting the specified requirements:
You should use the append mode to ensure that all new data is added to the table without affecting the existing rows.
You should set the mergeSchema option to true to allow the schema of the Delta table to be updated with the new columns found in the DataFrame.
The completed code would look like this:
df.write.format( " delta " ).mode( " append " )
option( " mergeSchema " , " true " )
saveAsTable( " Lakehouse1.TableName " )
insert code

Question 40

You have a Fabric tenant that contains a data pipeline.
You need to ensure that the pipeline runs every four hours on Mondays and Fridays.
To what should you set Repeat for the schedule?


Correct Answer: C
You should set Repeat for the schedule to Weekly (C). This allows you to specify the pipeline to run on specific days of the week, in this case, every four hours on Mondays and Fridays. Reference = Scheduling options for data pipelines are available in the Azure Data Factory documentation, which includes details on configuring recurring triggers.
insert code
  • ««
  • «
  • …
  • 4
  • 5
  • 6
  • 7
  • 8
  • 9
  • 10
  • 11
  • 12
  • 13
  • …
  • »
  • »»
[×]

Download PDF File

Enter your email address to download Microsoft.DP-600.v2026-10-12.q204 Dumps

Email:

FreeQAs

Our website provides the Largest and the most Latest vendors Certification Exam materials around the world.

Using dumps we provide to Pass the Exam, we has the Valid Dumps with passing guranteed just which you need.

  • DMCA
  • About
  • Contact Us
  • Privacy Policy
  • Terms & Conditions
©2026 FreeQAs

www.freeqas.com materials do not contain actual questions and answers from Cisco's certification exams.